
Mixture of Experts (MoE) Lightens the Compute Load for Local AI: The Same Can’t Be Said for Memory
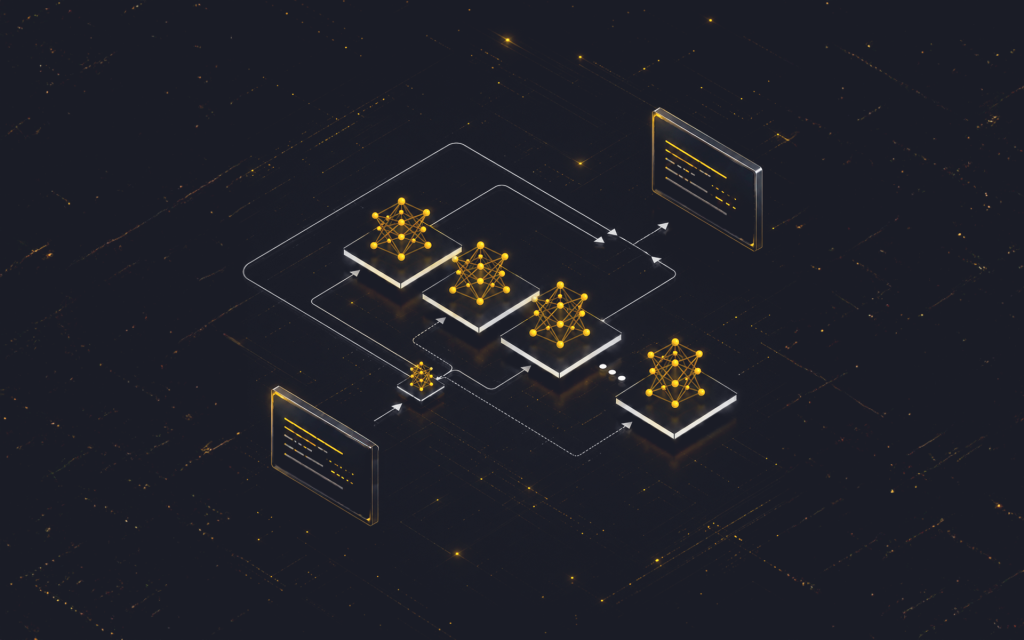
Mixture of Experts architecture delivers larger-model capability while activating only a fraction of the model’s parameters per token. That makes it a strong fit for local AI, but the full model still has to remain accessible in memory. Here’s why that matters and...
 English
 繁體中文
 简体中文
 日本語
 Deutsch
 한국어